Key Insights
Master defense in depth with clear steps, real-world examples, and expert tips to build a resilient security program.
Defense in depth helps security teams reduce breach risk by layering people, process, and technology into overlapping safeguards. When one control misses an attack or fails under pressure, another can detect, contain, or slow the intrusion. Generative AI has raised the stakes: attackers now clone writing styles and mass-produce convincing spear phishing emails, making single-layer defenses far easier to slip past.
Building that resilience means treating risk management, privileged access, workforce hygiene, incident response, and hardware-backed encryption as connected layers, not separate checklists.
Key Takeaways
- Combining people, process, and technology into overlapping safeguards means one control's failure doesn't have to become a full breach.
- Attackers now clone writing styles and mass-produce convincing spear phishing emails, making single-layer defenses easier to bypass.
- Hardware security modules protect sensitive keys and cryptographic operations from software-based attacks that compromise other layers.
- Organizations with extensive security AI and automation cut breach lifecycles by 80 days on average, according to IBM's 2025 Cost of a Data Breach Report.
What Is Defense in Depth?
Defense in depth can reduce breach risk by layering controls that compensate when one safeguard fails.
Defining Layered Security
Security teams often illustrate the concept with pre-digital border defenses: fortifications, towers, forts, and watch posts with overlapping fields of view, shared signal beacons, and on-demand reinforcements. When attackers overran one position, the next line absorbed the assault while defenders regrouped. Modern cybersecurity applies this same philosophy: each safeguard assumes another may falter.
The same logic applies to information security: firewalls alone could not counter rising malware, insider abuse, and remote-access threats. Today, the National Institute of Standards and Technology (NIST) defines defense in depth as a strategy that integrates people, technology, and operations capabilities across multiple layers and missions of the organization. The methodology layers heterogeneous security technologies across common attack vectors so attacks missed by one technology are caught by another. The goal mirrors the border-defense playbook: buy time, confuse adversaries, and contain damage until response.
Designing Graceful Failure
In practice, each layer should fail gracefully. For example, phishing-resistant multi-factor authentication (MFA) can challenge compromised credentials; behavior analytics can flag malware that missed a signature; and micro-segmentation can limit access from an exploited server. Distributing safeguards forces attackers to chain multiple exploits and raises the effort required to reach sensitive systems.
Few standalone controls cover the breadth of modern threats. Effective defense depends on overlapping technical tools, rigorously enforced procedures, and resilient physical protections working in concert across critical frontiers.
Vulnerability and Risk Management
Patching relentlessly and anchoring decisions in real risk data helps you stay ahead of attackers who constantly probe for unpatched weaknesses. The urgency is measurable: the Verizon Data Breach Investigations Report (DBIR) found that vulnerability exploitation surpassed stolen credentials as the top breach entry point for the first time in 19 years of reporting, now accounting for nearly one-third of all breaches. Even in electronic trading, where downtime is measured in seconds, a single unaddressed vulnerability can halt transactions and trigger cascading financial losses.
Effective prioritization comes down to four practices:
- Design For Continuous Patching: The first safeguard is an environment built for uninterrupted updates. Redundant clusters let you patch operating systems or firmware without disrupting front-line services, while blue-green deployments and rolling container updates handle application-level changes. Teams can treat maintenance windows as a fallback rather than the primary strategy.
- Assess Risk Continuously: Effective patching depends on continuous risk assessment that tells you what to fix first. A tight cycle begins with complete asset inventory and classification that maps servers, SaaS tenants, and rogue IoT devices to business owners.
- Model Threats Against Real Adversaries: This foundation supports threat modeling that pairs likely adversaries with the techniques they favor, drawing from frameworks such as MITRE ATT&CK. Impact and likelihood ratings convert technical findings into business language executives understand, while a living risk register updates as assets appear, threats evolve, or controls mature.
- Prioritize By Exploitation Evidence: Contextualizing scan results with these ratings helps you avoid chasing raw severity scores. Pair severity with exploitation data instead: the Cybersecurity and Infrastructure Security Agency's (CISA) KEV catalog — short for Known Exploited Vulnerabilities — lists flaws with reliable evidence of active exploitation, and the Exploit Prediction Scoring System (EPSS) model from the Forum of Incident Response and Security Teams (FIRST) estimates the probability that a published CVE will be exploited in the wild within 30 days. Linking this context to automated workflows in SOAR platforms drives risk-based patching: critical findings open tickets instantly, predefined playbooks isolate affected hosts, and teams enforce remediation SLAs without manual oversight.
Layered defenses work best when each layer stays current. Combining business-driven risk assessment with automated vulnerability management helps you close gaps before adversaries exploit them, without putting uptime on the negotiating table.
Importance of Multiple Layers in Defense in Depth
Complementary control categories make defense in depth more resilient against multi-vector attacks. A firewall that drops malformed packets does little when an employee clicks a well-crafted phishing link, and endpoint antivirus may not stop lateral movement if network segmentation is absent.
Combining Independent Controls
Independent defenses reduce the blast radius because each layer compensates for others' blind spots. You strengthen that redundancy by mixing vendors and control types so a single exploit is less likely to cascade across identical technologies. If an attacker bypasses one vendor's intrusion prevention signature, the next layer, a behavior-based EDR from another supplier, still pressures them to reveal themselves. The result is graceful degradation rather than catastrophic failure.
Modern architecture typically includes:
- Perimeter Security: Firewalls and intrusion prevention systems filter traffic at the edge.
- Network Segmentation: Internal firewalls and virtual LAN (VLAN) zoning limit movement between trusted zones.
- Endpoint Protection: Endpoint detection and response (EDR) and host-based firewalls identify suspicious behavior on user and server systems.
- Application Security: Secure coding reviews and web application firewalls reduce exposure in production apps.
- Data Security: Encryption and data-loss prevention protect sensitive information when other controls fail.
- User Training: Continual phishing simulations and policy education reinforce secure behavior.
- Monitoring And Response: Security operations center (SOC) analysts backed by security information and event management (SIEM) and automated playbooks investigate and contain suspicious activity.
Extending Monitoring Coverage
These controls function as interlocking rings, each one reinforcing the others. When one ring is breached, monitoring catches the anomaly, segmentation limits spread, and encryption keeps stolen files unreadable during an active compromise.
Misconfigured MX records can expose corporate email to spoofing and interception, yet another reason monitoring should extend beyond endpoints. By baselining account activity across SaaS tenants, you can surface suspicious behavior long before credentials are abused. This layered strategy for cybersecurity remains a practical foundation for an effective enterprise security program.
Managing Super Users
Controlling super-user access is one of the most important internal safeguards, because a compromised admin can quietly weaken other layers you deploy. A super user, sometimes called a super admin, holds unrestricted privileges across critical systems, making their account a prime target. If an attacker hijacks that credential, they can disable logs, delete data, or exfiltrate sensitive information without immediate detection.
Organizations can reduce this risk with a privilege blueprint that covers the full admin lifecycle:
- Least Privilege: Grant only the permissions required for the role, and keep administrative identities separate from day-to-day user accounts.
- Just-In-Time Elevation: Implement privilege escalation that issues elevated access only when specific tasks, such as patching, configuration, or recovery, require it, then revokes those privileges when the work is complete.
- Phishing-Resistant MFA: Elevated accounts should enforce phishing-resistant MFA. CISA designates FIDO/WebAuthn and PKI-based MFA as stronger options because they resist phishing, push bombing, and SIM-swap attacks that defeat OTP and push-based methods.
- Hardened Administration: Administrative sessions should run from hardened workstations with no routine internet browsing. Record each session for audit purposes.
- Privileged Logging: SIEM logging should capture privileged activity as it happens, and security teams should review this data on a defined cadence.
- Fast Deprovisioning: When roles change, de-provision access promptly to reduce orphaned keys and unused admin paths.
These measures help keep super-user governance consistent and protect the defense-in-depth layers that depend on trusted administration.
Employee Training and Security Hygiene
Training your workforce is a direct way to reinforce your defense-in-depth program. When you give employees the skills to spot a phishing link, protect personal information, and escalate suspicious activity, you shrink the attack surface attackers depend on. According to the FBI's Internet Crime Complaint Center (IC3), business email compromise (BEC) generated $3.05 billion in losses, and the bureau specifically flags AI chat generators that produce official-sounding emails mimicking a company's CEO.
Building Threat Awareness Programs
An effective program starts with threat awareness. Brief each department on the tactics most likely to reach them: finance teams get wire-fraud drills, developers see secure-coding failures. Tying lessons to daily tasks keeps attention high and matches training to actual job risk.
Next, translate policy into practice. Walk employees through acceptable-use rules, data-handling tiers, and password requirements, then test retention with continuous phishing simulations, like the classic advance-fee scam, that turn theory into reporting habits when a real alert fires. Consider a hypothetical scenario: a phishing wave impersonating a well-known bank could exploit brand trust to harvest credentials and bypass technical controls. Set realistic goals: the SANS Institute warns that a perfect click-rate target can be unrealistic and potentially harmful, and that repeat clickers, not first-time clickers, represent the greater organizational risk.
Implementing Security Hygiene Controls
Security hygiene cements the gains from training by turning security expectations into daily habits. Organizations can require multi-factor authentication, enforce unique passphrases, and push automatic patches to help minimize endpoint vulnerabilities. Coaching teams on safe use of email and internet, device encryption, and physical safeguards like badge discipline helps human behavior align with technical controls.
Security hygiene also improves reporting quality. Employees who understand what suspicious activity looks like can escalate faster and provide better context to analysts. That context helps SOC teams separate mistakes from malicious activity and reinforces the broader defense-in-depth model.
By pairing ongoing education with daily hygiene, you create a human firewall that continues protecting data even if a technical control fails. Treat it as one layer among many: AI-generated lures are increasingly difficult for even trained users to spot, so technical controls should stand behind human judgment.
Incident Response and Recovery
A tested incident response and recovery plan turns defense-in-depth theory into decisive action when an attack slips through. NIST refreshed its incident guidance with an approach that aligns response with governance, identification, protection, detection, response, and recovery so lessons learned feed back into risk management rather than sitting in a post-mortem file.
Preparing Response Workflows
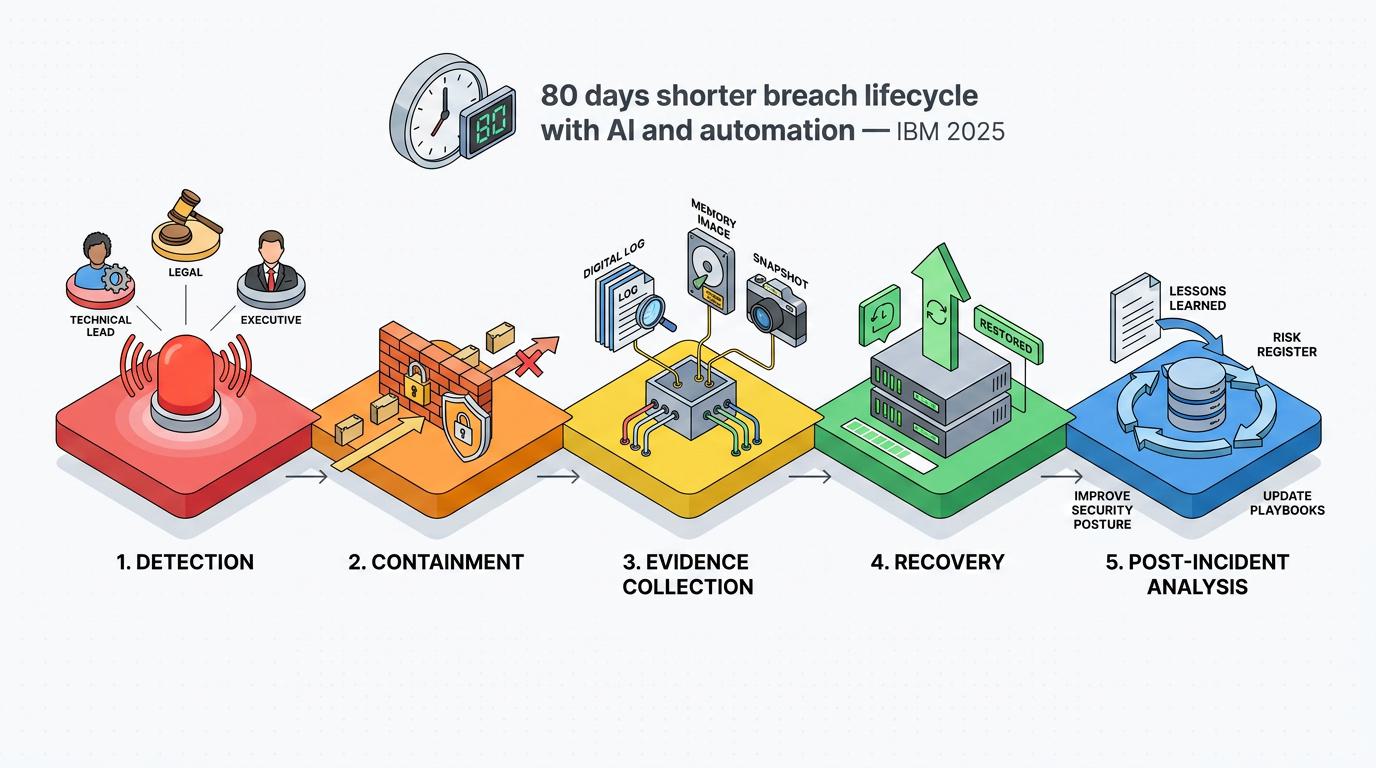
Every plan starts by assigning clear roles: who leads technical containment, who communicates with legal, and who briefs executives. Defined ownership reduces hesitation when minutes matter. Equally critical are concise communication protocols; single channels for status updates prevent conflicting narratives while preserving evidence.
Employees should understand exactly how to escalate suspicious activity. Tabletop exercises prepare marketing, finance, and engineering teams to know which hotline or chat room to use, so a phishing email never languishes in an inbox.
Executing Recovery Steps
Once the alarm sounds, responders move through repeatable steps:
- Containment Procedures: Halt attacker movement and reduce the scope of compromise.
- Evidence Collection: Preserve logs, memory images, and other forensic material needed for investigation.
- Recovery Processes: Restore affected services with short, documented procedures that business owners understand.
- Post-Incident Analysis: Feed lessons back into the risk register and update the controls that failed or underperformed.
Stakeholders should rehearse triage playbooks that align with the broader security architecture, closing gaps between technical response and business recovery.
Speed and Continuous Improvement
Speed matters most in containment: every additional hour an attacker moves laterally raises the eventual cleanup cost, and slow disclosure now invites tighter compliance scrutiny. The IBM report found that organizations with extensive security AI and automation shortened breach lifecycles by an average of 80 days compared to those without.
Post-mortems then fine-tune upstream layers, patch cadence, network segmentation, and user training, creating a feedback loop that hardens your security program. By weaving incident response throughout your layered architecture, a single public breach becomes a contained interruption instead of a major business disruption.
The Role of Hardware-Based Encryption
Hardware-based encryption gives you a hardened security layer that operates beneath the operating system, shielding keys and cryptographic operations from the software stack attackers target most.
Keys stay inside sealed silicon rather than moving through general-purpose system memory. By keeping them inside a protected microprocessor, hardware encryption reduces exposure to memory-scraping and privilege-escalation attacks that routinely compromise software-only solutions.
These devices are built for abuse. Under the current NIST FIPS 140-3 standard, higher-assurance cryptographic modules can use hard, opaque enclosures and environmental failure protections that detect out-of-range voltage or temperature and shut the module down. Upon tamper detection, normal operations halt and critical security parameters are erased. This design helps prevent malware on the host from reading, replaying, or modifying ciphertext because decryption stays isolated from ordinary software processes. The result is a layer that operates independently from patches, AV signatures, or user behavior, which is exactly the kind of redundancy defense in depth demands.
Deploying Hardware Encryption Strategically
Dedicated encryption hardware can help protect environments where a single breach could trigger regulatory fines, trading halts, or loss of intellectual property. Self-encrypting drives for laptops, hardware security modules for certificate authorities, and encrypted USBs for field teams all help demonstrate that key material is protected by dedicated hardware.
A strategic deployment plan should account for risk, assurance, and operational fit:
- High-Risk Assets: Prioritize laptops with sensitive data, certificate authorities, payment systems, and field devices that leave controlled environments.
- Validated Modules: Specify currently validated modules for new procurements. NIST's Cryptographic Module Validation Program (CMVP) listings help teams verify the validation status of cryptographic modules before purchase.
- Regulated Environments: Industries bound by privacy, healthcare, or financial oversight often require defensible data-at-rest controls, and Payment Card Industry (PCI) standards mandate HSM-backed protections for certain payment environments.
- Layered Cryptography: Software-based cryptography still matters for transit traffic and legacy workloads, but dedicated hardware is better suited to data and systems that require stronger key isolation.
Blending both approaches, guided by data sensitivity and compliance needs, gives you a layered encryption fabric that attackers would struggle to unravel with a single exploit.
Building Resilient Defense in Depth Through Integrated Layers
Integrated defense in depth depends on well-maintained controls, current encryption standards, and email security that complements the broader stack. Hardware-encrypted storage adds an inner ring: keys stay sealed inside tamper-resistant silicon, out of reach of OS-level malware and brute-force attempts.
Abnormal adds an email security layer to the picture. Its behavioral AI learns workflow cadences, vendor interaction patterns, and recipient behavior across your organization, and it is designed to surface the sophisticated, payloadless threats that often evade a legacy email gateway (SEG). It deploys via API as another discrete layer, enriching your SOC with context alongside existing tools, and scales across Microsoft and Google Workspace cloud email environments. Abnormal was named a Customers' Choice in the 2026 Gartner® Peer Insights™ Voice of the Customer for Email Security.
Ready to help close these gaps? See an Abnormal demo and experience how behavioral AI strengthens your defense-in-depth program.