Behavioral AI models how a specific person, account, or system normally acts, then flags activity that breaks from that pattern. Instead of checking every event against one fixed rulebook, it learns what is ordinary for a given entity and treats the gap between current and expected behavior as the signal worth investigating.
The approach spans academic research into decision-making and industry systems that predict, detect, authenticate, or personalize based on past activity. It powers fraud detection, insider threat programs, continuous authentication, and adaptive learning tools, but a deviation score is a starting point for review, not proof of intent.
Key Takeaways
Behavioral AI compares current activity with an entity's own established pattern instead of relying only on universal rules.
Its core process collects behavioral signals, builds a baseline, scores deviations, and adapts as behavior changes.
A deviation provides a reason to investigate, but it does not establish intent or prove wrongdoing.
Privacy, explainability, human review, and governance determine whether a deployment produces fair and useful outcomes.
Behavioral AI Definition and Scope
Behavioral AI is a class of systems that learn an entity's established pattern of activity, then score new activity by how far it departs from that pattern, updating the baseline as behavior changes.
In cybersecurity, a behavioral AI system protecting a corporate inbox learns that a finance director typically emails a short list of vendors during business hours, approves invoices through a known workflow, and signs in from two recognized devices. When a message arrives that mimics one of those vendors but asks to redirect payment to a new account, sent at an unusual hour from an unfamiliar session, the system treats the combined deviation as a signal worth surfacing for review, even though no single element matches a known malicious signature.
The Behavioral AI Processing Loop
Behavioral AI works through a repeating loop that collects signals, builds an entity-specific baseline, scores new activity, and updates its judgments on a schedule suited to the deployment.
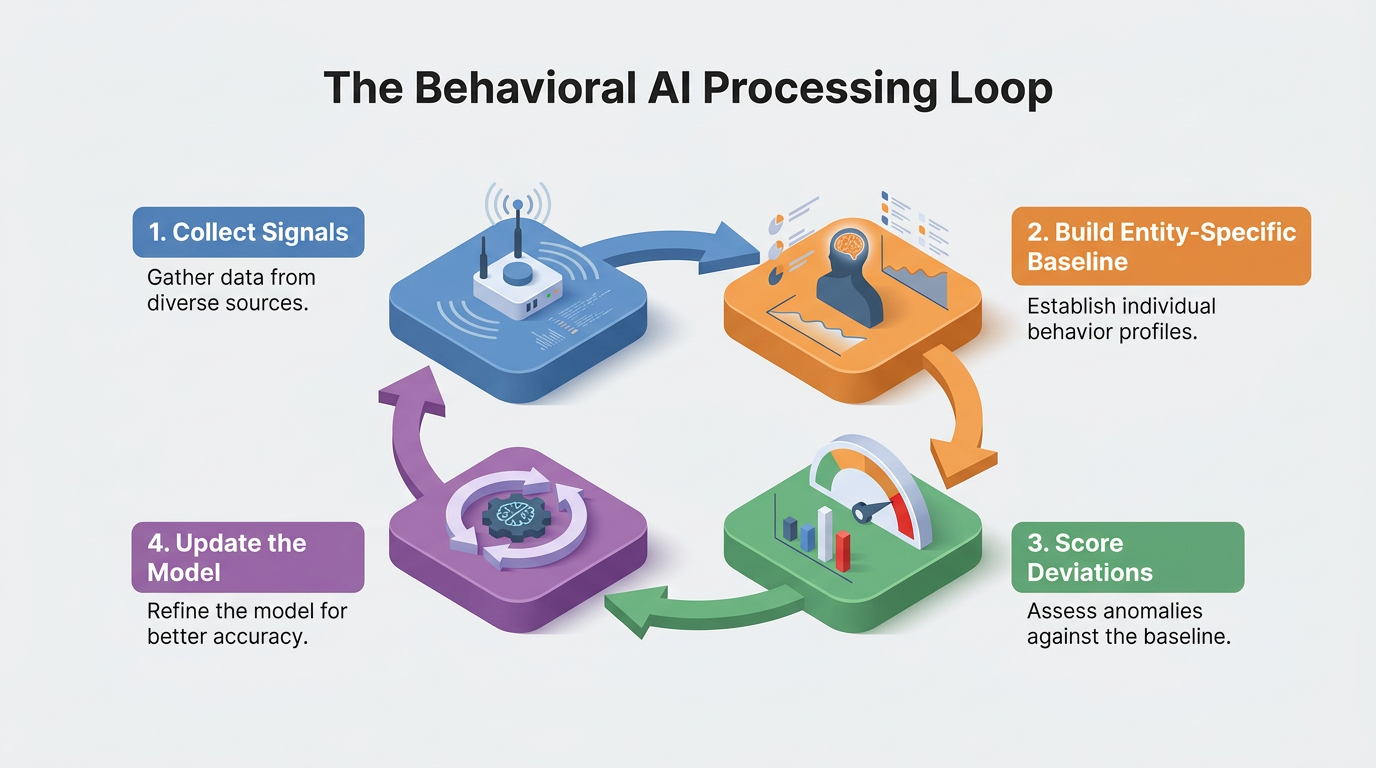
Entity-Specific Baselines Reflect Roles and Habits
Baselines start from raw activity records, then narrow to the expected pattern for one specific entity.
The raw material is any reliable record of action. Behavioral systems can ingest sensor readings, network traffic, system telemetry records, security alerts, email information, transactions, and biometric traits. Device signals can include keystroke cadence, phone angle, screen pressure, mouse movement, and gyroscope position. Session monitoring adds login time, device, location, and internet protocol address.
From those signals, the system builds a baseline that represents the expected state for one person, account, device, or peer group. In an industrial network, for example, the model can learn ordinary traffic volumes, ports, processes, and connections. A large transfer, new port, off-hours login, or unfamiliar process then stands out because it differs from that specific environment.
Entity-specific baselines matter because organization-wide averages hide differences between roles. An activity that is routine for an administrator may be unusual for a new employee. In practice, useful systems combine individual history with carefully chosen peer groups so that the model can recognize both personal habits and role-based expectations. Clear data governance practices also determine which signals the system may collect, retain, and use.
Deviation Scores Turn Differences into Responses
Deviation scoring works through two different taxonomies at once: a family of machine learning methods that compute the score, and a set of anomaly categories that describe what kind of difference the score is catching. The methods side of that pairing covers several common approaches:
Supervised Models: These models learn boundaries from confirmed good and bad examples, which can help when teams have dependable labels.
Unsupervised Models: These models learn the structure of the data and suit environments where new or rare anomalies lack labels.
Clustering and Density Methods: These methods identify observations far from comparable activity.
Sequence Models: Models such as long short-term memory (LSTM) networks track the order of actions, allowing a chain of ordinary steps to appear unusual when the sequence changes.
Reinforcement Learning: This approach adjusts decisions through rewards and penalties tied to confirmed outcomes.
Deviation scores translate the output of any of these methods into responses such as additional authentication, session termination, or analyst review, using machine learning methods chosen for the available data. The system must also distinguish among three anomaly categories, since the same underlying method can miss a deviation that only shows up at the wrong scope:
Point Anomaly: A single value falls far outside the norm.
Contextual Anomaly: An activity appears ordinary in one setting but unusual in another.
Collective Anomaly: Individually legitimate events become suspicious when they occur together.
The system compares the final score with a threshold and can trigger additional authentication, end a session, or create a ticket for review.
Model Updates Balance Drift and Alert Quality
Model updates must accommodate legitimate behavioral change without allowing suspicious activity to become part of the baseline.
Concept drift describes a change in the underlying data distribution. It can follow a new job, device, schedule, workflow, or attack technique, and the initial signal often looks the same whether the cause is harmless or harmful.
Production teams address drift with online learning, periodic retraining, and drift detectors that update models incrementally. The trade-off is that updating too quickly can absorb suspicious behavior into the baseline, while updating too slowly can create unnecessary alerts. Review rules therefore need to separate temporary exceptions from durable changes in ordinary activity.
Real-time processing does not represent a separate type of behavioral AI. It describes how quickly the same collection, baselining, scoring, and updating loop runs. A system can process live streams when immediate action matters or use scheduled batches when the decision allows more time. The core model remains the same, but the operational response changes with the deployment.
Types of Behavioral AI
Behavioral AI types differ according to whether they predict, detect, authenticate, personalize, infer, simulate, or imitate behavior. They include:
Predictive Behavioral Modeling: Models forecast future outcomes from past performance, engagement, transactions, or interactions.
Anomaly Detection: Systems flag activity that does not fit a learned definition of normal, such as an unusual purchase amount or location.
Behavioral Biometrics and Continuous Authentication: Devices assess whether the expected user remains present through keystroke dynamics, mouse movement, touch, and other traits, often alongside multi-factor authentication.
User and Entity Behavior Analytics: User and entity behavior analytics (UEBA) builds profiles for people and non-human entities such as servers and devices to surface insider threats or data exfiltration.
Recommender and Personalization Systems: Platforms use purchase, viewing, and browsing behavior to model preferences and rank what to show next.
Emotion-Aware Computing: Affective systems infer states such as boredom, agitation, or relaxation and adjust their responses, although regulators restrict some uses.
Agent-Based Behavioral Simulation: Generative agents reproduce plausible human behavior for research into opinions, decisions, and group dynamics.
Imitation Learning: An agent learns a task by mimicking human demonstrations recorded during gameplay, navigation, or physical work. These categories can overlap. A continuous authentication system, for example, may use anomaly detection and predictive scoring at the same time. A recommender can combine preference modeling with real-time adaptation.
Where Behavioral AI Is Used
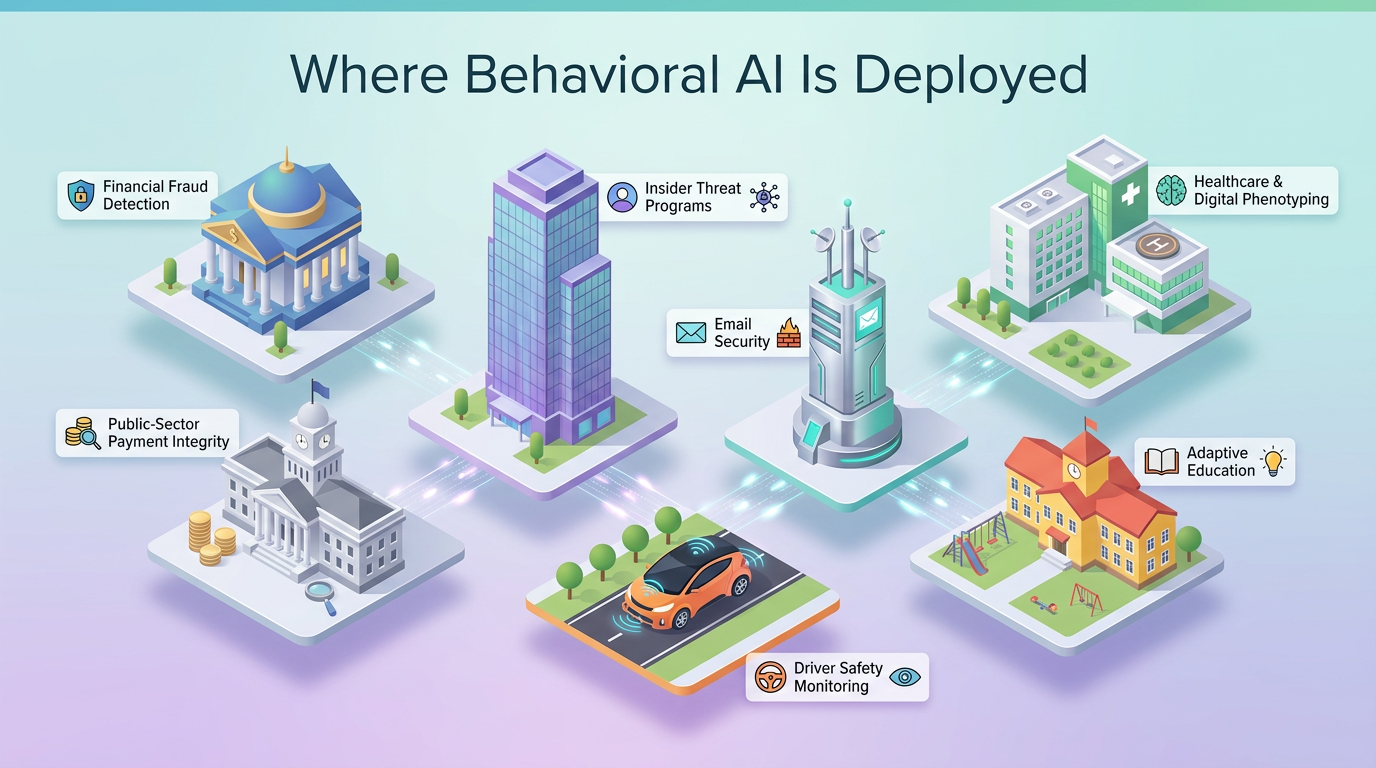
Organizations use behavioral AI to detect risk, personalize interactions, and evaluate likely outcomes wherever they hold a history of actions. Common deployments span several industries:
Financial Fraud Detection: Banks group card transactions by cardholder behavior, timing, location, and amount, then score deviations tied to payment fraud or account takeover. Explainability becomes the tradeoff when the bank must justify a decision to a customer or regulator.
Public-Sector Payment Integrity: Government agencies use anomaly detection to identify potentially improper payments.
Insider Threat Programs: Behavioral models can detect slow patterns that simple daily thresholds miss and combine log data with facility access, travel, and human resources records before alerting an analyst.
Email Security: Mail systems used for email security learn who communicates with whom, about what, and when, allowing the system to evaluate messages through relationship and context rather than payload alone.
Healthcare and Digital Phenotyping: Smartphones collect accelerometer, global positioning system, touch, and voice data that models can combine with brief self-reports, although clinical validation remains limited.
Adaptive Education: Intelligent tutoring systems use a student's performance history to provide feedback and adjust the learning pathway, though instructors may find the reasoning difficult to interpret.
Driver Safety: In-vehicle monitoring analyzes facial images and movement to identify distraction or drowsiness and alert the driver. The acceptable threshold, response, and level of human review depend on the consequence of a mistake.
Across these use cases, the common thread is that behavioral AI earns its value by matching the sensitivity of its scoring to the stakes of the decision. The same loop of signal collection, baselining, and deviation scoring looks very different in a payments queue than it does in a classroom or a vehicle cabin.
Behavioral AI vs. Related Approaches
Behavioral AI differs from related approaches mainly in the data it learns from and the output it produces.
Approach | Learns From | Produces |
|---|---|---|
Behavioral AI | Records of past behavior for a specific person, entity, or group | A baseline of normal, predictions of behavior, or deviation scores |
Rule-Based Systems | Logic a human expert writes in advance | A fixed pass-or-fail decision when activity meets a stated condition |
Signature-Based Detection | Features from known attacks | Matches against known patterns without a model of novel activity |
Predictive AI | Historical data of any kind | Forecasts and classifications without generating new content |
Generative AI | Large corpora of text, images, audio, or code | New content in response to a prompt |
Behavioral analytics and behavioral AI often overlap, although behavioral analytics can also include dashboards and conventional statistical reporting. UEBA represents the enterprise-security portion of behavioral AI. Predictive AI is the broader class. Generative AI creates content instead of evaluating behavior, though one system can combine both capabilities.
Limitations and Misconceptions of Behavioral AI
Behavioral AI remains limited by false positives, incomplete history, uncertain intent, and the legal obligations attached to sensitive behavioral data.
Human Review for Uncertain Signals
Two limits keep a deviation score from standing in for human judgment.
Certain Prediction: Behavioral AI cannot predict an individual's actions with certainty.
Proven Intent: A deviation does not reveal whether a person acted because of a legitimate change, negligence, or malicious intent.
Privacy Rules and Explainability Constrain High-Stakes Uses
Behavioral data includes browsing history, device usage, location and travel, purchases, health tracking, and communication patterns. Collecting and combining those signals can reveal more than any single record, so legitimate use depends on clear disclosure, appropriate consent, limited retention, access controls, and a defined purpose.
The Federal Trade Commission (FTC), in its 2023 biometric policy statement, includes behavioral characteristics within biometric information and identifies privacy, data security, bias, and discrimination as enforcement concerns. The EU AI Act also restricts emotion recognition in workplaces and schools outside specified medical and safety uses, along with AI that manipulates behavior or exploits vulnerabilities.
Bias and explainability add operational limits. A model can reproduce differences already present in historical data or use proxies that disadvantage a group. The National Institute of Standards and Technology (NIST) AI Risk Management Framework identifies fairness with harmful biases managed as a characteristic of trustworthy AI and organizes risk work around Govern, Map, Measure, and Manage. These controls matter most when a score can affect employment, access, finances, education, or healthcare.
Better Baselines Lead to Better Decisions
Behavioral AI is most useful when its baseline reflects the right entity, its scoring remains explainable, and its alerts receive review proportional to their consequences. As deployments expand, strong evaluation will depend less on whether a system detects difference and more on whether it can distinguish meaningful change from ordinary human variation.
Frequently Asked Questions
Does Behavioral AI Need to Identify a Person by Name?
No. A system can model an account, device, session, household, or peer group without attaching the pattern to a named person. Privacy risk still exists because a detailed behavioral profile may allow reidentification or reveal sensitive habits.
How Can an Organization Audit a Behavioral Model?
An audit can examine which signals the model uses, how it defines peer groups, when it updates baselines, how thresholds change, and what happens after an alert. Version histories and documented review outcomes help connect model changes with real-world consequences.
How Long Does a Behavioral Baseline Take to Stabilize?
There is no universal stabilization period. The time depends on how often the entity acts, how much its routine varies, and whether a suitable peer group can provide temporary context while the system gathers enough individual history.