Behavioral AI in threat intelligence addresses an uncomfortable fact: malicious activity can look legitimate while it unfolds. This use of behavioral AI helps identify activity that deserves attention without overwhelming analysts or treating ordinary variation as proof of compromise. Used well, behavioral AI can improve how early and confidently security teams recognize threats.
Key Takeaways
Behavioral baselines built from a user's own history, peer-group activity, and organization-wide patterns give telemetry the context to separate ordinary variation from suspicious deviation.
Single events rarely prove an attack; scored and correlated sequences of related signals turn activity data into evidence worth investigating.
Analysts remain responsible for validating ambiguous findings and approving consequential responses, and their feedback makes future detections better.
Governance frameworks and operational metrics determine whether behavioral detection stays accurate, explainable, and defensible as environments and attackers change.
What Behavioral AI in Threat Intelligence Means
Behavioral AI models expected activity and identifies meaningful deviations that become useful threat intelligence when evaluated with context. It applies machine learning to telemetry such as logins, process activity, and network traffic, learns what normal looks like for each user and system, and flags departures worth investigating. Signature-based detection works differently: a signature is a pattern that corresponds to a known or codified attack, so it primarily catches threats that match previously identified patterns. Behavioral detection compares observed events against a learned definition of normal instead, which lets it surface activity no one has seen before. These approaches complement each other.
User and entity behavior analytics (UEBA) applies anomaly detection to users, hosts, Internet Protocol (IP) addresses, and applications, while adversary behavior models describe what attackers do regardless of tooling. Cyber threat intelligence is threat information analyzed and enriched enough to support decisions, and behavioral signals can be one useful input.
How Behavioral AI Turns Activity into Actionable Intelligence
Behavioral AI turns raw activity into actionable intelligence by establishing context, scoring meaningful deviations, correlating related signals, and supporting analyst decisions. Each stage narrows the gap between a log entry and a judgment someone can act on.
Behavioral Baselines Establish Context for Detection
A baseline begins with telemetry collected from across the environment:
Authentication logs
Endpoint process events
Network flows
Cloud application programming interface (API) calls
File access records
The analytics pipeline normalizes that data into a consistent schema, and the model selects features that carry behavioral meaning:
Login times
Device identity
Geolocation
Access frequency
Process behavior
Relationships between entities
None of those features means much alone. A 2 a.m. login is routine for a night-shift administrator and strange for an accountant, which is why baselines compare each event against the user's own historical activity and the behavior of peers in similar roles. Organization-wide patterns add another reference point. Sequence matters too. Models that learn the typical order of actions can flag unfamiliar actions and familiar actions appearing in unfamiliar chains.
Baselines also have to move: models continuously update last quarter's snapshot as roles and work patterns change, and most baselines need days to weeks of observation before their scores deserve trust. Isolated events carry less weight than sustained changes across multiple features.
Risk-Scored Signals Support Analyst Decisions
Once a baseline exists, each deviation receives a risk score weighted by how rare and how consequential it is. Correlation engines link related anomalies across data sources into a single case, and enrichment adds external context such as IP reputation or a mapping to known adversary techniques. Scores that cross a threshold escalate to an analyst; lower scores stay quiet and limit noise.
Escalation also reflects:
Confidence in the underlying data
The sensitivity of the affected asset
The potential severity of the activity
Whether independent signals reinforce one another
A moderate anomaly involving a critical system may therefore outrank a rarer event on a low-value asset. This context helps teams prioritize cases by probable impact, with novelty as one consideration.
An account authenticates from an unfamiliar network at 5 a.m., a mild anomaly on its own. The same account then browses a file share it has not touched in months, another mild anomaly. A new scheduled task appears on a server that account administers, and compressed archives begin moving outbound. Each event remains within existing rules. The correlated sequence scores high enough to open a case with the full evidence chain attached.
The analyst's verdict closes the loop. A confirmed compromise validates the detection logic; a benign explanation, perhaps a new contractor workflow, becomes a suppression or a threshold adjustment informed by human judgment.
Where Behavioral AI Detects Threats Across Identity and Systems
Behavioral AI supports identity activity and system investigations by connecting deviations that reveal insider activity, credential abuse, malware, lateral movement, and persistent intrusions.
Identity Behavior Exposes Insider and Credential Abuse
From an access log's point of view, a malicious insider and a stolen credential look identical: valid authentication followed by unusual activity. Behavioral models catch both by watching for:
Off-hours access
Unusual privilege use
Impossible travel between distant login locations
Deviations from what peers in the same role do
Behavioral indicators can appear before sabotage, and some are non-technical, such as supervisor conflicts and repeated rule violations. Programs may pair technical baselines with relevant personnel signals under appropriate privacy controls.
One unusual event is rarely conclusive. An engineer querying an unfamiliar repository once may reflect a project change. When the same account also disables logging and exports large volumes of data, the pattern builds a case, because each signal raises the probability the others are malicious. A sharp break from a user's whole pattern can indicate account takeover, while slow boundary-pushing can indicate insider activity. A patient attacker can shift behavior gradually enough to drag the baseline along. The distinction depends on pace, context, and the relationship among signals.
System Behavior Reveals Malware, Lateral Movement, and Persistent Intrusions
At the system level, behavioral models analyze code behavior. Process activity and API-call sequences can classify malware behavior even after a file's hash changes, and mass file encryption can flag ransomware before any signature for that variant exists. Credential dumping surfaces the same way: a process reading credential store memory outside of trusted security tools is suspicious behavior regardless of the binary's name.
This matters most against attackers who bring no malware at all. The Cybersecurity and Infrastructure Security Agency (CISA) Volt Typhoon advisory noted that conventional indicators of compromise are generally lacking for living-off-the-land activity, and that organizations without established baselines struggle to tell legitimate use of built-in tools from malicious use. Lateral movement yields to the same approach through authentication graphs, where models flag low-probability authentication events between hosts that rarely talk to each other.
Hashes, domains, and IP addresses are generally easier for attackers to rotate than the techniques an intrusion requires. Those techniques tend to change more slowly. Behavioral hunting is therefore useful against advanced persistent threats built to outlast indicator-based defenses.
Behavioral AI Across the Threat Intelligence Lifecycle
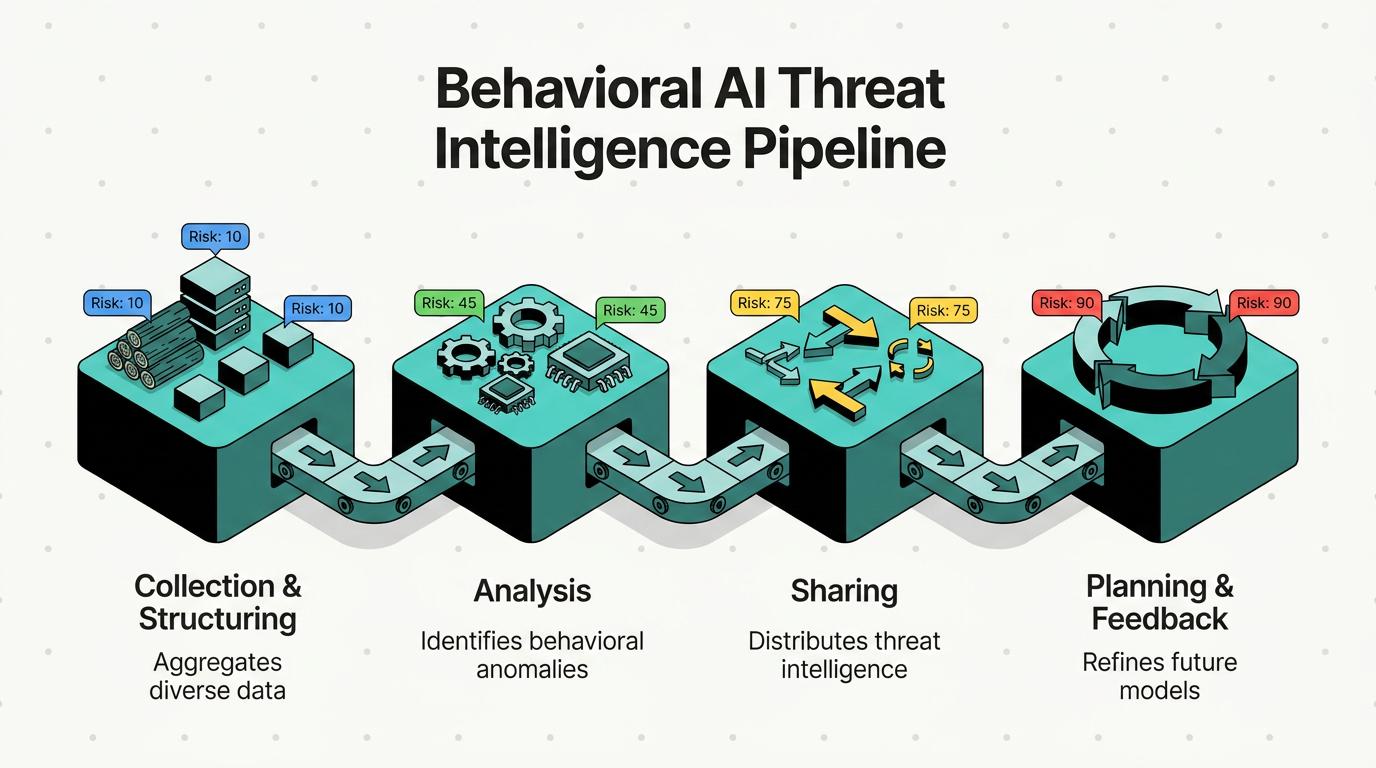
Behavioral AI creates value across the intelligence lifecycle by converting normalized telemetry into contextual findings that can be analyzed, shared, acted on, and improved through feedback.
The lifecycle moves through four stages:
Collection and Structuring: Aggregating logs through protected centralized logging with security information and event management (SIEM) tools, including a SIEM platform, can reduce adversaries' opportunities to tamper with evidence and help preserve the data that makes behavior analytics possible. Structuring and enrichment then prepare that data for analysis by extracting entities and mapping relationships.
Analysis: UEBA and correlation engines score and connect findings during this stage.
Sharing: Confirmed findings move into security orchestration playbooks, threat intelligence platforms, and partner exchanges. Structured Threat Information Expression (STIX) provides a format for shared intelligence, while Trusted Automated Exchange of Intelligence Information (TAXII) defines how it moves between parties. Governance and trust determine what actually gets shared, because behavioral findings can carry sensitive personal data.
Planning and Feedback: Incident outcomes, including confirmed incidents and suppressed false positives, return to the program and document discovered coverage gaps. Those outcomes inform model retraining and help teams reprioritize what to collect next.
Each stage feeds the next: a gap in one, such as unlogged telemetry or unscored findings, degrades everything downstream.
Human Oversight and Explainable Behavioral AI
Human oversight makes behavioral AI defensible by adding business context, validating ambiguous findings, controlling consequential actions, and improving future detections through feedback. A model can score a deviation, but only an analyst knows that unusual finance-system access is explained by an acquisition, or that disabling an executive's account mid-negotiation costs more than the risk score shows. Analysts also document decisions, which makes detections auditable later.
For that work, an analyst needs specific evidence:
Which features drove the score
Which events formed the sequence
Which peers or historical windows supplied the comparison
Which adversary techniques the pattern may map to
Explanations at that level let a person confirm a finding far faster than rebuilding it from raw logs. They also make it easier to challenge an unreliable model output before it triggers a consequential response.
Analyst verdicts tune thresholds, suppress recurring false positives such as backup jobs that mimic exfiltration, and expose quieter failures, like a log source going dark and slowly eroding a baseline.
Risks and Limitations of Behavioral AI
Behavioral AI stays trustworthy only when organizations manage false positives, shifting baselines, poor data, and attacks on the models themselves, along with the tradeoffs those defenses impose.
False Positives, Drift, and Poor Data Weaken Baselines
Real attacks are rare relative to benign activity, so even a model with a low false-positive rate can produce alerts that are mostly benign in absolute terms. Left unmanaged, that volume produces alert fatigue, and fatigued analysts start missing the alerts that matter.
Normal is also unstable. Reorganizations can change behavior faster than models expect. New tools and shifting work patterns can do the same, a problem known as concept drift. Data quality compounds the problem. Missing telemetry and sampling bias in what was collected can distort a baseline, while weak or absent labels can also cause it to misrepresent the environment it claims to model.
The countermeasures rely on operational practices:
Monitoring model performance
Reviewing thresholds on a schedule
Defining retraining triggers for detected drift
Insisting on representative training data
Teams need to distinguish a model problem from a telemetry problem before changing thresholds or retraining on incomplete data. Programs can measure detection performance through precision and recall while also tracking analyst workload; raw alert counts can hide declining performance as alert volume increases.
Evasion and Poisoning Target the Models Themselves
Deployment-time evasion occurs when an attacker crafts inputs that flip a model's classification with minimal perturbation. Training-data poisoning corrupts the data a model learns from. An attacker who changes behavior gradually can also walk a baseline forward until the model accepts activity it should have flagged.
Poisoning can be quiet and patient. An attacker with access during a model's training window might perform small daily reads of a sensitive repository. The baseline might then learn that this access is normal for that account. Months later, the bulk exfiltration those reads rehearsed scores far lower than it should because the model learned the attacker's preparation as legitimate behavior.
Pipeline defenses include:
Input validation
Training-data provenance tracking
Restricted write access
Testing resistance to evasion and poisoning
Audit trails
An escalation path for suspected model compromise
None of this is free. Proposed mitigations can trade resistance to manipulation against accuracy and add computational cost. More interpretable models are easier to audit and defend. Their effect on detection varies by model and use case, and interpretability can involve an accuracy tradeoff.
A Framework-Grounded Implementation Plan
A reliable implementation starts with protected telemetry, then adds validated baselines, analyst workflows, framework-based governance, and measurable review criteria. Teams can follow a sequence:
Identify the behaviors and decisions that matter most.
Centralize protected telemetry.
Validate baselines in an observe-only period.
Connect detections to analyst workflows.
Review outcomes on a fixed schedule.
Established frameworks keep that progression honest:
National Institute of Standards and Technology (NIST) Cybersecurity Framework: Frames continuous monitoring and adverse event analysis as organizational outcomes.
NIST AI Risk Management Framework: Governs models through its govern, map, measure, and manage functions.
MITRE ATT&CK: Maps detection coverage against known adversary techniques.
MITRE ATLAS: Catalogs adversary tactics against AI-enabled systems, useful because behavioral models are themselves targets.
These frameworks work together rather than in isolation, and a program missing any one of them has a corresponding blind spot in governance, model risk, or technique coverage.
Review criteria worth tracking:
Alert Quality: Teams track how many escalations turn out to be genuine findings.
Coverage Gaps: Security teams map detection coverage against known adversary techniques to find blind spots.
Drift Indicators: Model owners review baseline degradation and analyst override rates on a schedule.
Confirmed Detections: Validated incidents show which detection logic is earning its place.
Tracked together, these criteria give security leaders an evidence-based view of whether behavioral detection is actually improving over time rather than simply generating more alerts. Without them, programs risk mistaking activity for progress and miss the early signals that a model, a data source, or a workflow has quietly stopped earning its keep.
Measurable Impact and the Future of Behavioral Intelligence
IBM's 2025 breach report found that organizations reached a mean time to identify and contain a breach of 241 days, the fastest pace in the report's nine years of tracking, with AI-powered defenses cited as a driver of the improvement. Containment figures like that are measured outcomes. Vendor performance claims are a separate category, and adoption and implementation maturity still vary across organizations.
The direction of travel runs toward predictive analysis, AI-assisted triage, and agentic security operations that can coordinate multi-step workflows while keeping humans accountable for critical decisions. Autonomous agents expand the attack surface and complicate auditing, which argues for firm limits on autonomous response and governance that keeps every consequential action reviewable.
From More Alerts to Better Decisions
Behavioral baselines give telemetry context, correlation turns scattered deviations into connected evidence, analysts convert evidence into defensible decisions, and governance keeps the whole chain honest as attackers probe the models themselves. Organizations should judge behavioral AI by the quality and defensibility of the decisions it supports.
Frequently Asked Questions
How Does Behavioral AI Differ From Signature-Based Threat Detection?
Signatures match patterns of known or codified attacks, so they primarily catch threats that match patterns someone has already identified. Behavioral AI looks for deviations from learned normal activity and connected sequences of events, which lets it surface attacks with no known indicator.
What Data Does Behavioral AI Use for Threat Intelligence?
Common sources include identity and authentication logs, endpoint process events, network traffic, cloud and application activity, and external threat feeds, though not every environment needs every source.
Can Behavioral AI Detect Insider Threats?
Yes. Baselines for users and entities can surface unusual access, privilege use, or data movement that precedes insider incidents, and those findings still require privacy safeguards and human review before anyone acts.
Why Does Behavioral AI Produce False Positives?
Legitimate behavior changes constantly, telemetry is often incomplete, and baselines can be weak or outdated. Because genuine attacks are rare compared with benign activity, even accurate models flag some ordinary events as suspicious.
Can Behavioral AI Replace Security Analysts?
Behavioral AI can prioritize alerts and connect related evidence. Analysts remain necessary for business context, ambiguous findings, consequential decisions, and the feedback that improves the models.